|
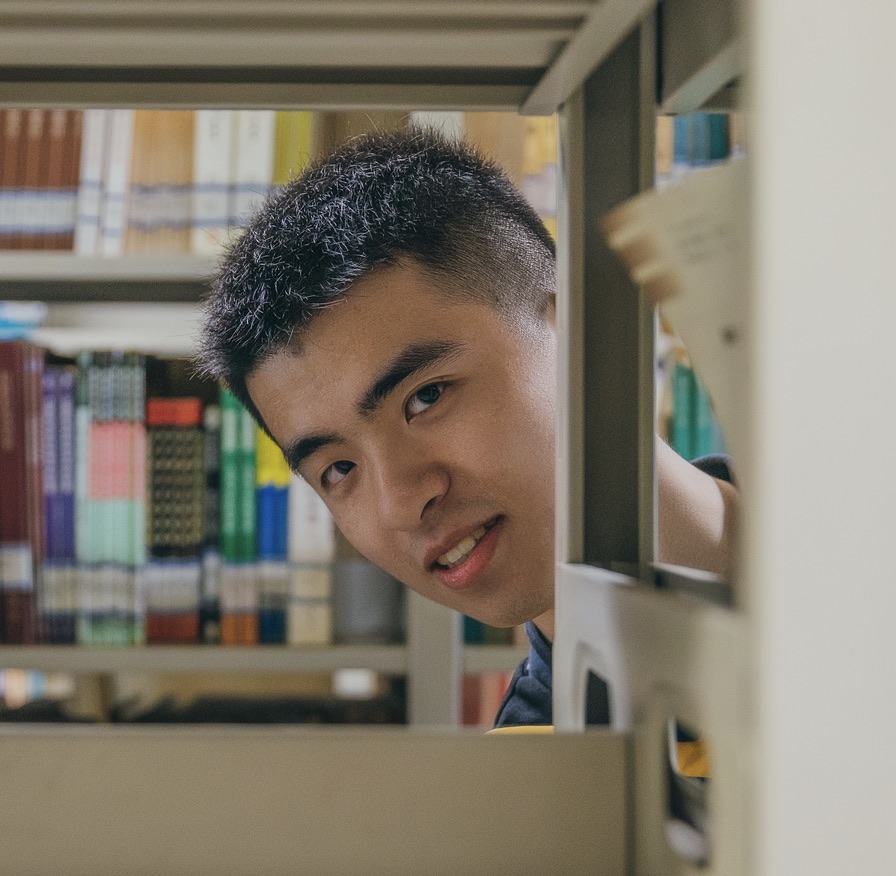
I am a research scientist at Google DeepMind, building state-of-the-art coding agents to solve challenging problems in physics. Previously, I worked at Meta Superintelligence Labs on agents for automating AI research and self-improvement through reinforcement learning and continual learning. I am the main contributor to the SWE coding capabilities of Muse Spark 1.0, 1.1, 1.2, 1.3, and Muse Wonder. I did my PhD at the Computer Science Department, University of Maryland, College Park. I can be reached at {bob}{my-first-name+my-last-name}@gmail.com. My name in Chinese: 陈力畅 Google Scholar / Twitter / LinkedIn / Github |
|
|
My research interests are in reinforcement learning, self-improving coding agents, and AI for scientific discovery. My current focus is building coding agents that can tackle challenging physics problems and accelerate scientific research. |
|
Research Scientist @ Google DeepMind, Present. Building coding agents to solve challenging problems in physics.
|

|
|
|
|
|
|
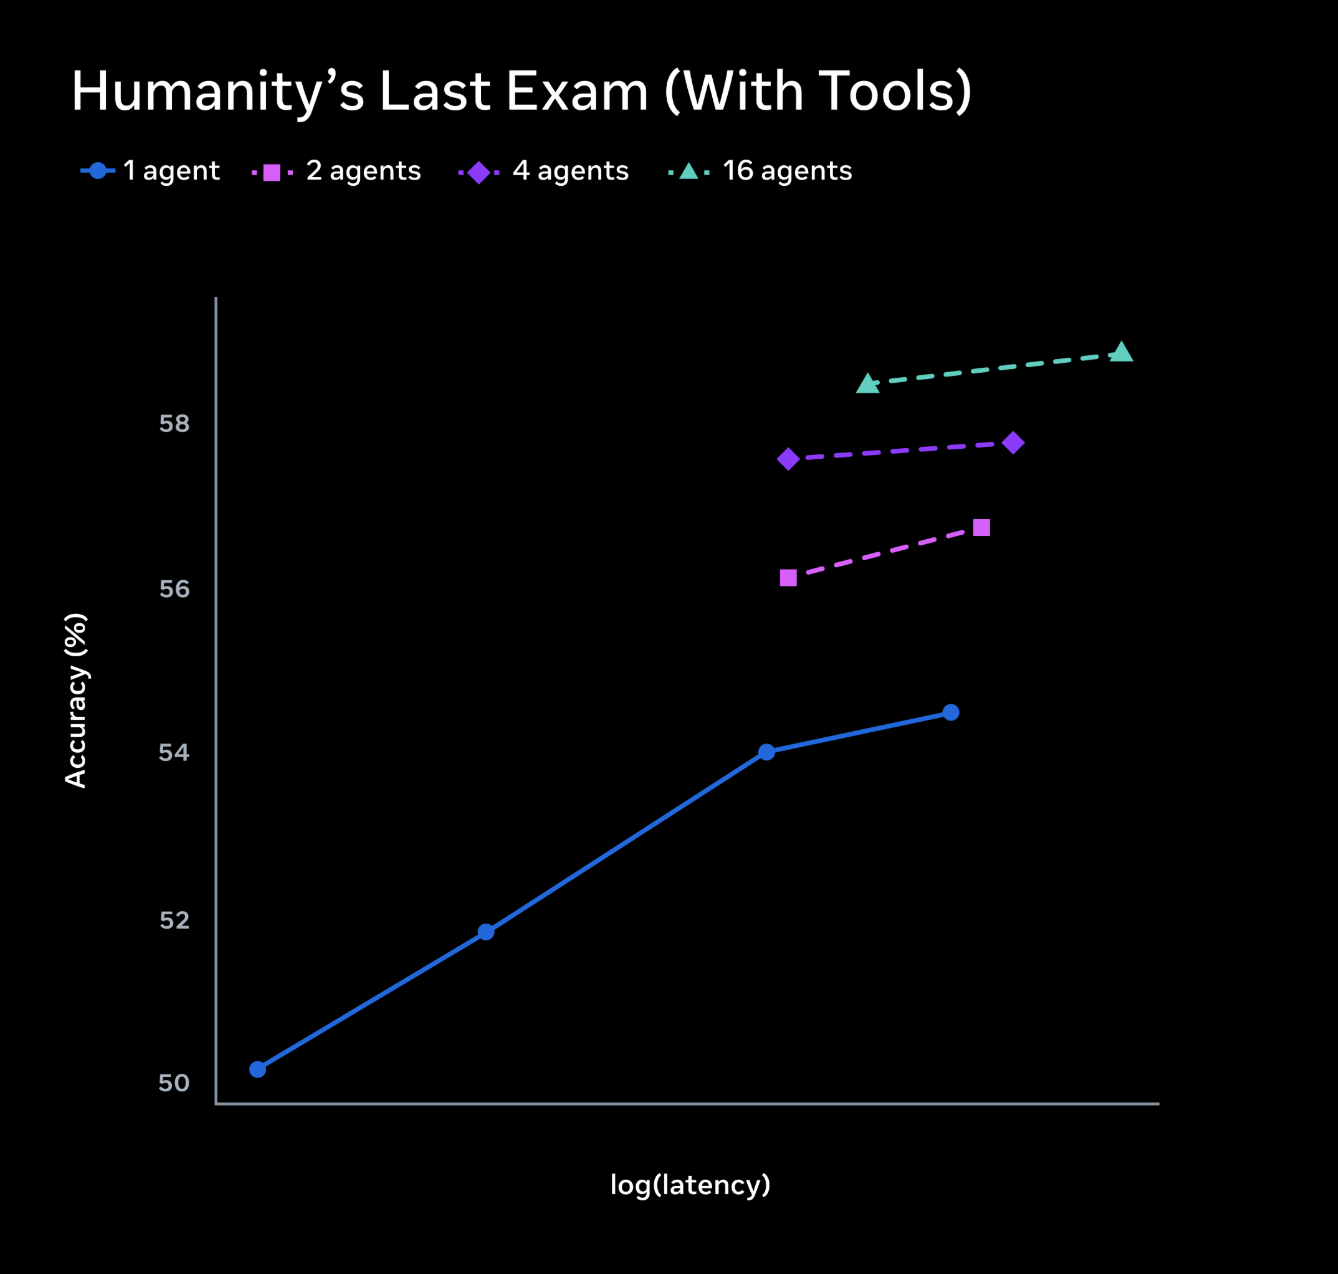
|
Main Contributor to the Contemplating mode Meta Superintelligence Labs, 2026 |
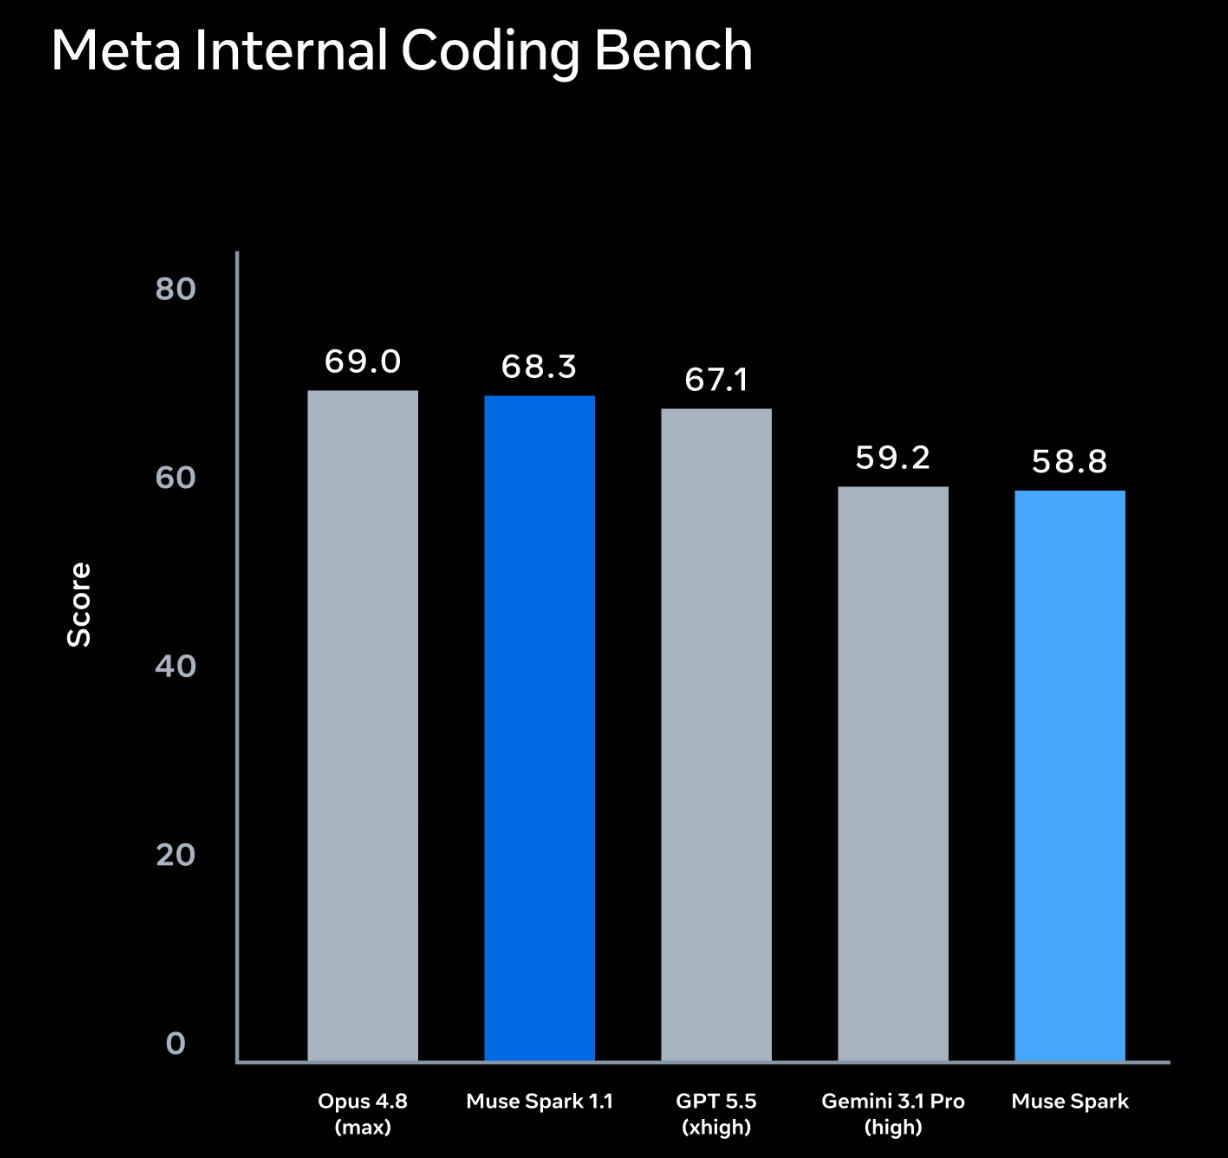
|
Main Contributor to the SWE agents Meta Superintelligence Labs, 2026 |
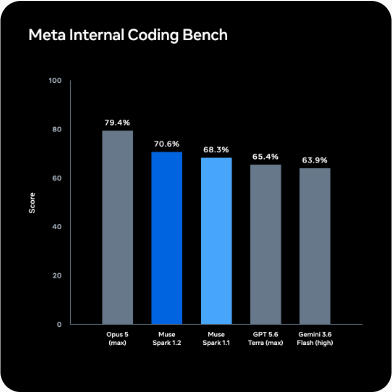
|
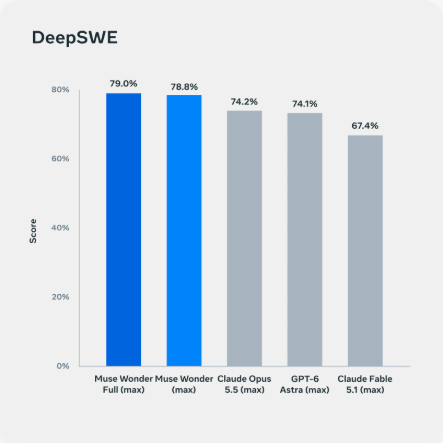
Main Contributor to the SWE coding capabilities Meta Superintelligence Labs, 2026 |
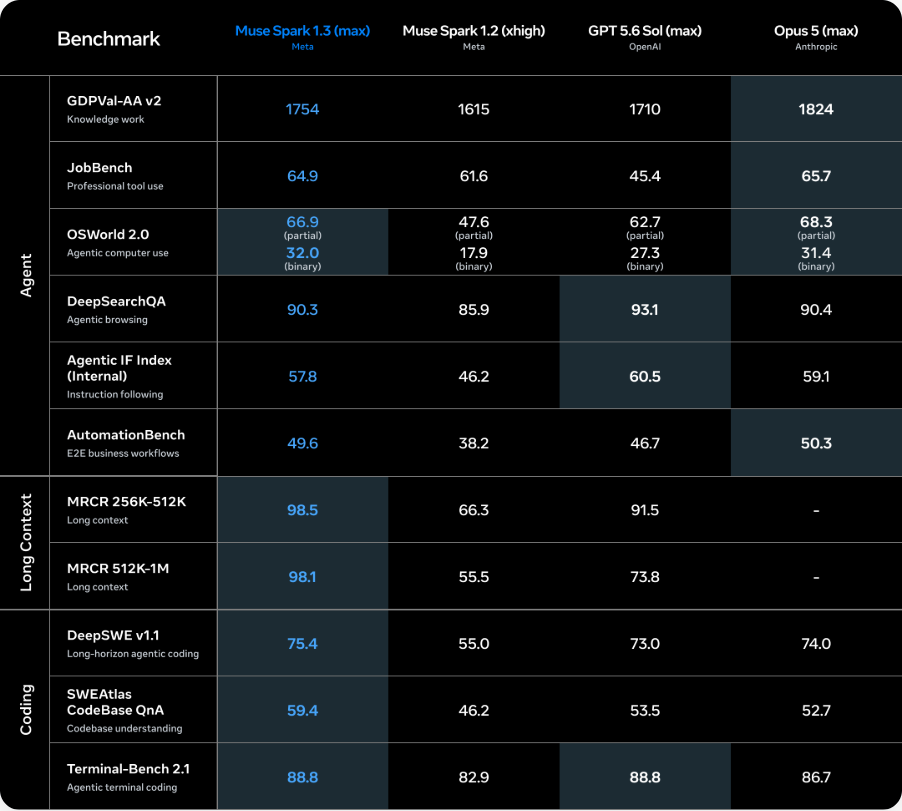
|
Main Contributor to the SWE coding capabilities Meta Superintelligence Labs, 2026 |
|
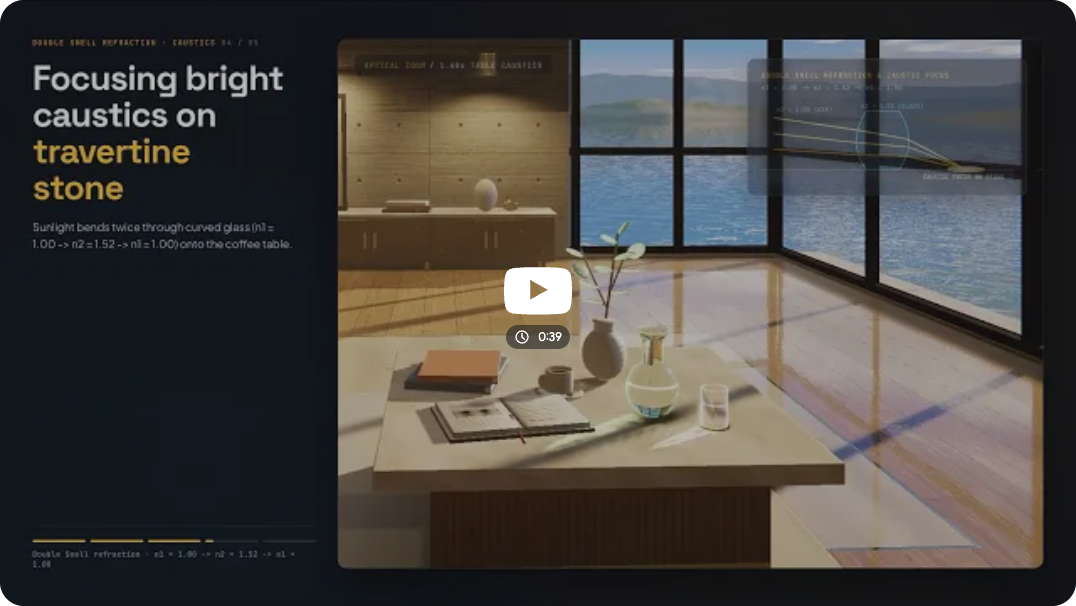
Main Contributor to the SWE coding capabilities Meta Superintelligence Labs, 2026 |
|
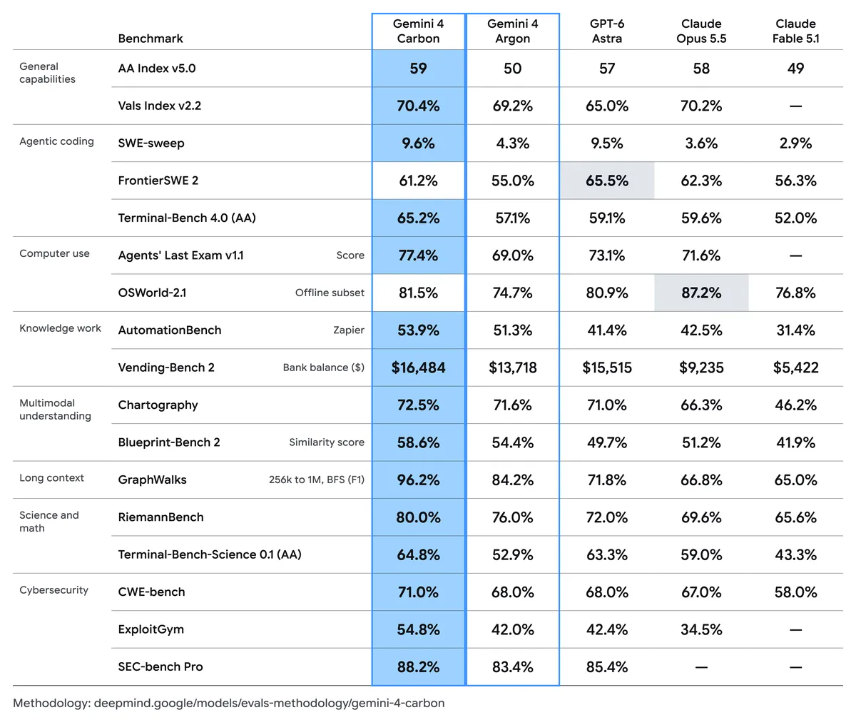
Google DeepMind, 2026 |
|
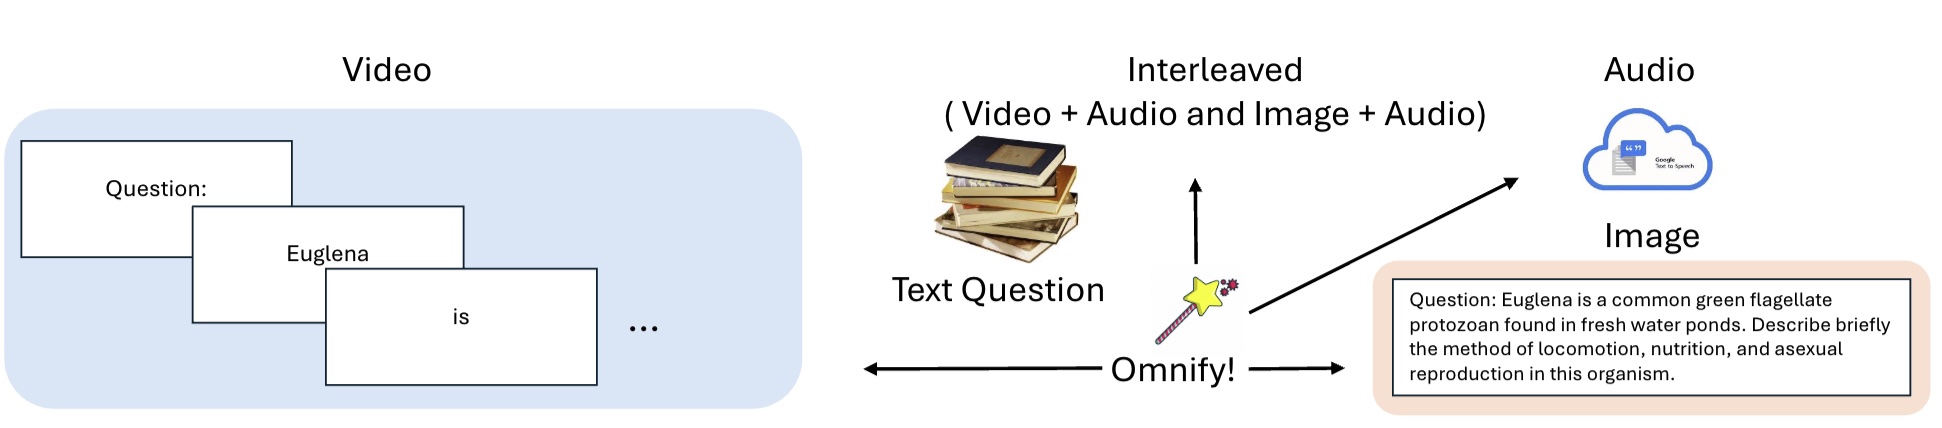
Google DeepMind, 2026 |
|
Lichang Chen, Hexiang Hu, Pranav Shyam, Ming-Hsuan Yang, Boqing Gong, et al. Work Done@Google Deepmind, ICLR 2025 |
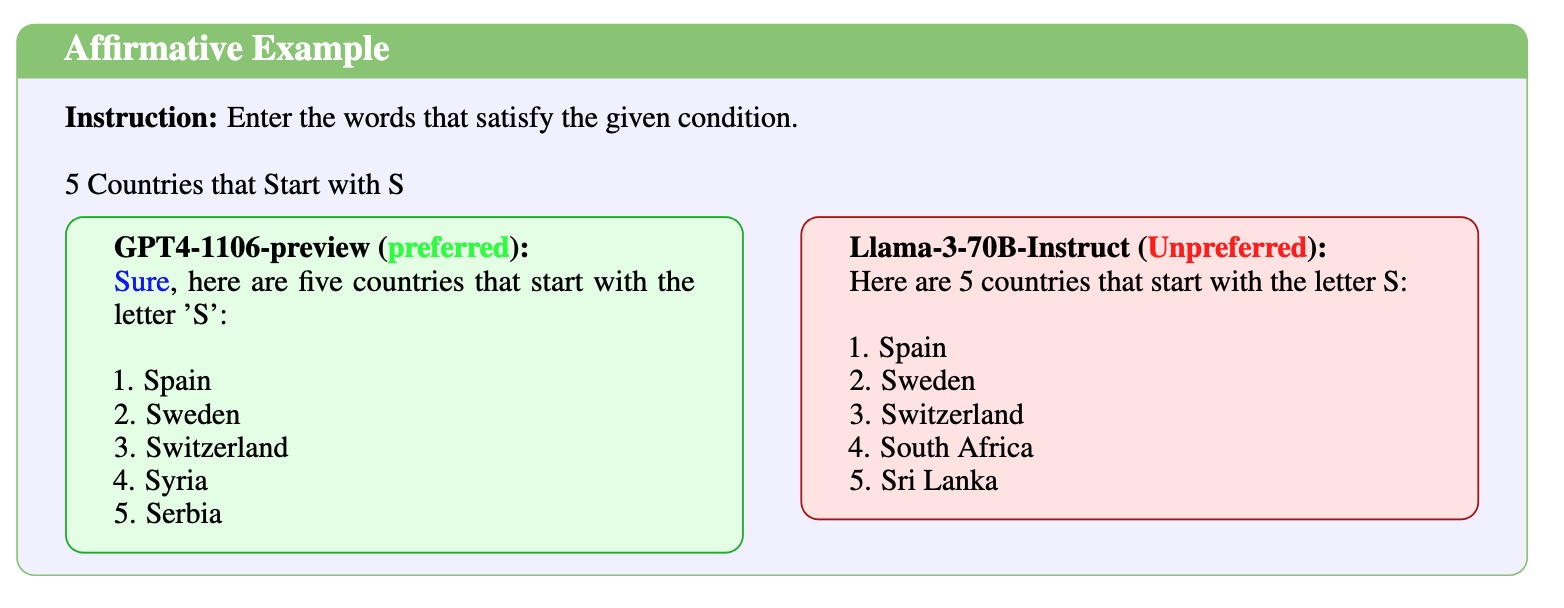
|
Lichang Chen*, Xuanchang Zhang*, Wei Xiong*, Tianyi Zhou, Heng Huang, Tong Zhang. ACL, 2025 |
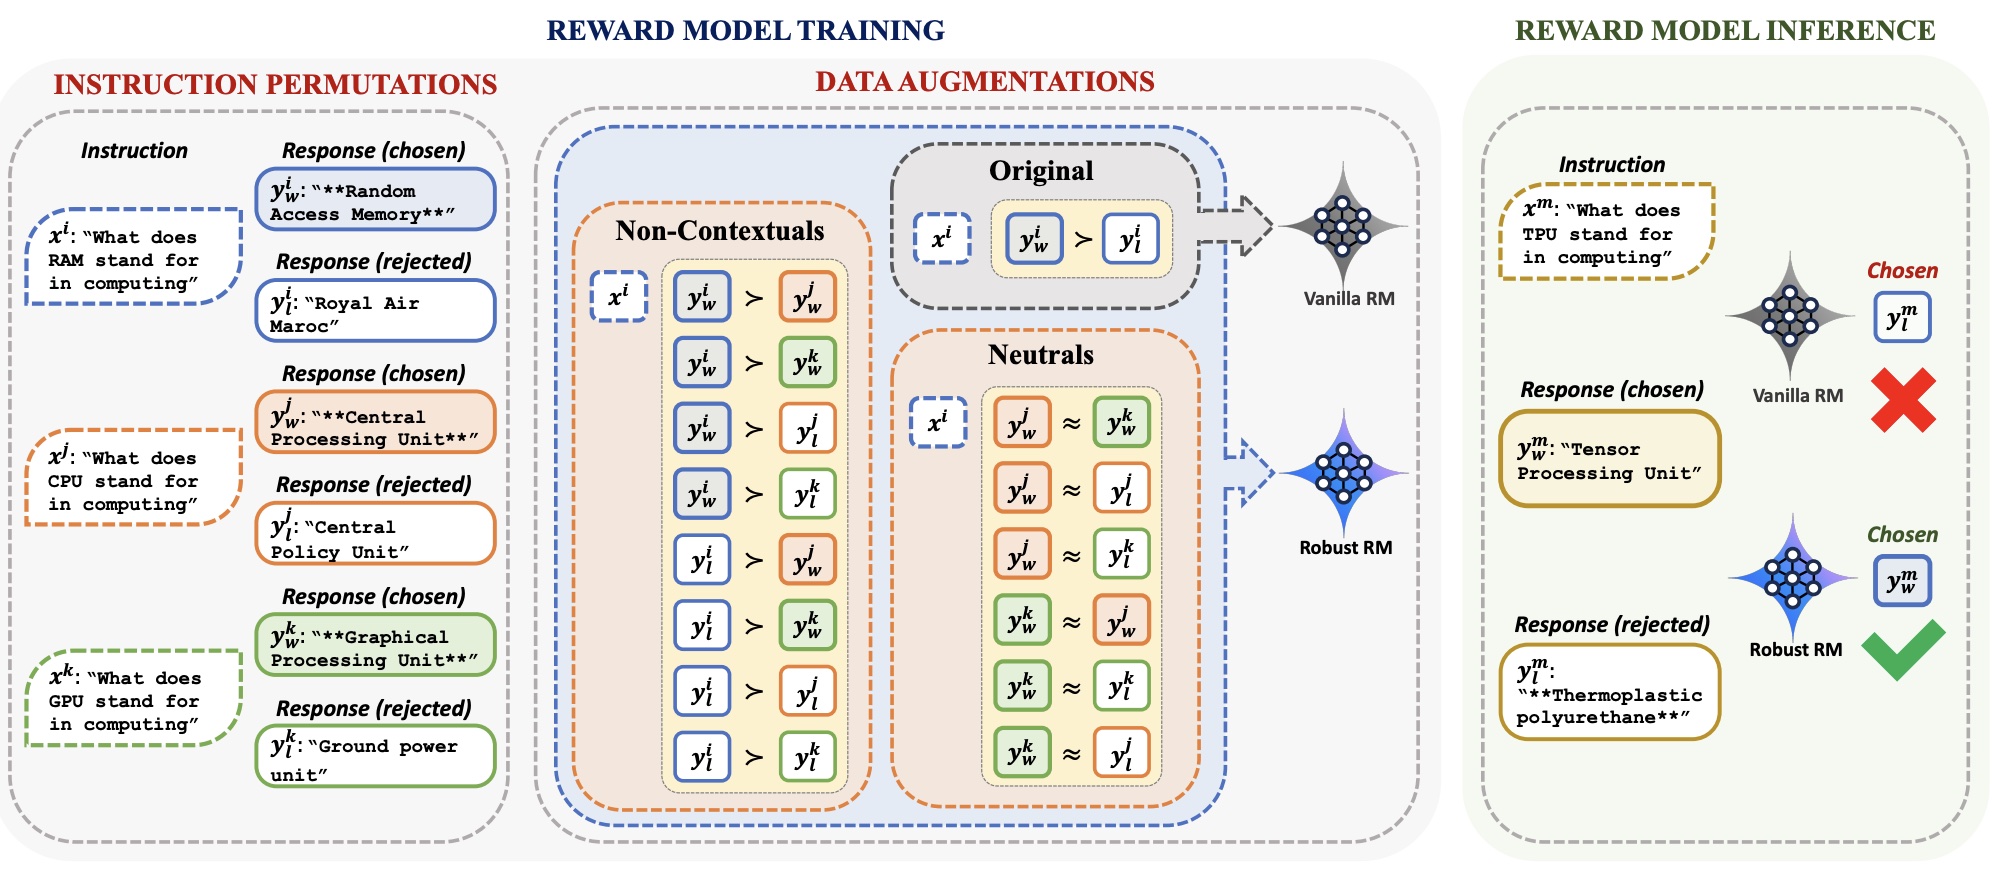
|
Tianqi Liu, Wei Xiong, Jie Ren, Lichang Chen, Tianhe Yu, Mohammad Saleh, et al. Work Done@Google Deepmind, ICLR 2025 |
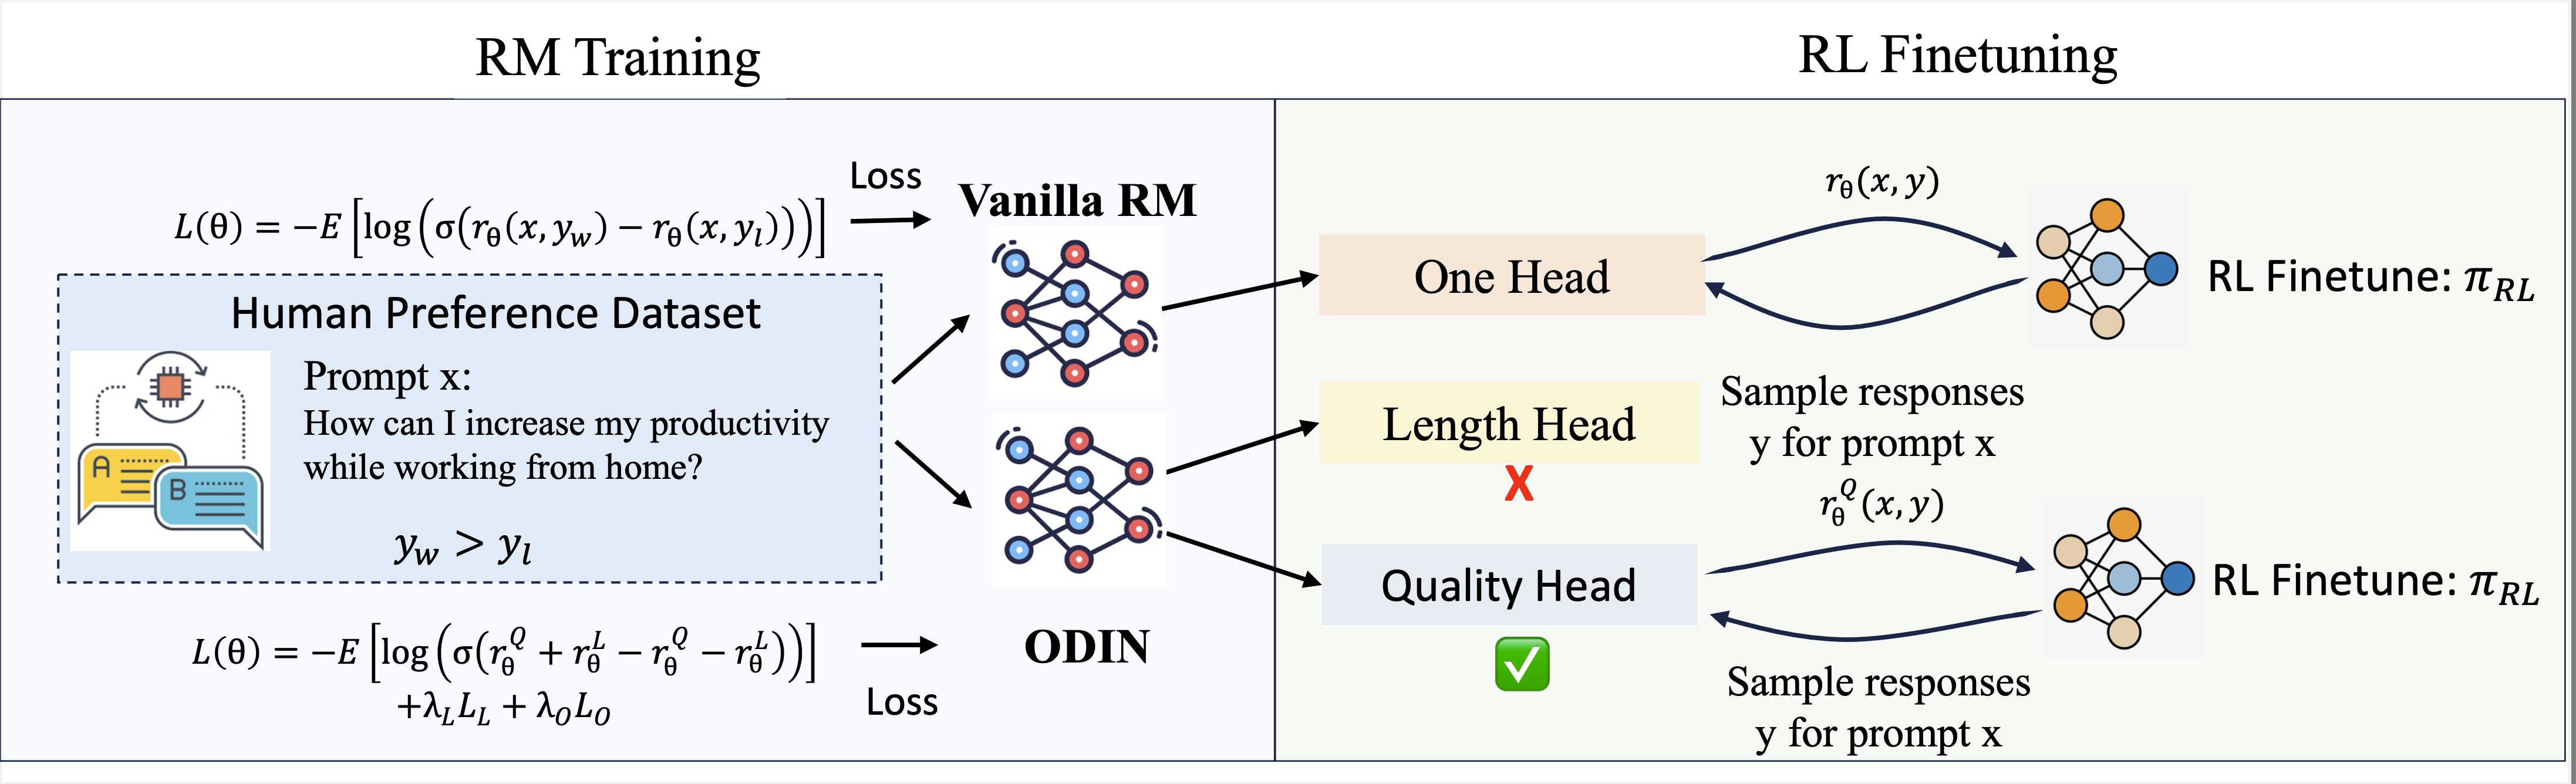
|
Lichang Chen*, Chen Zhu*, Davit Soselio, Tianyi Zhou, Tom Goldstein, Heng Huang, Mohammad Shoeybi, Bryan Catanzaro ICML, 2024. |
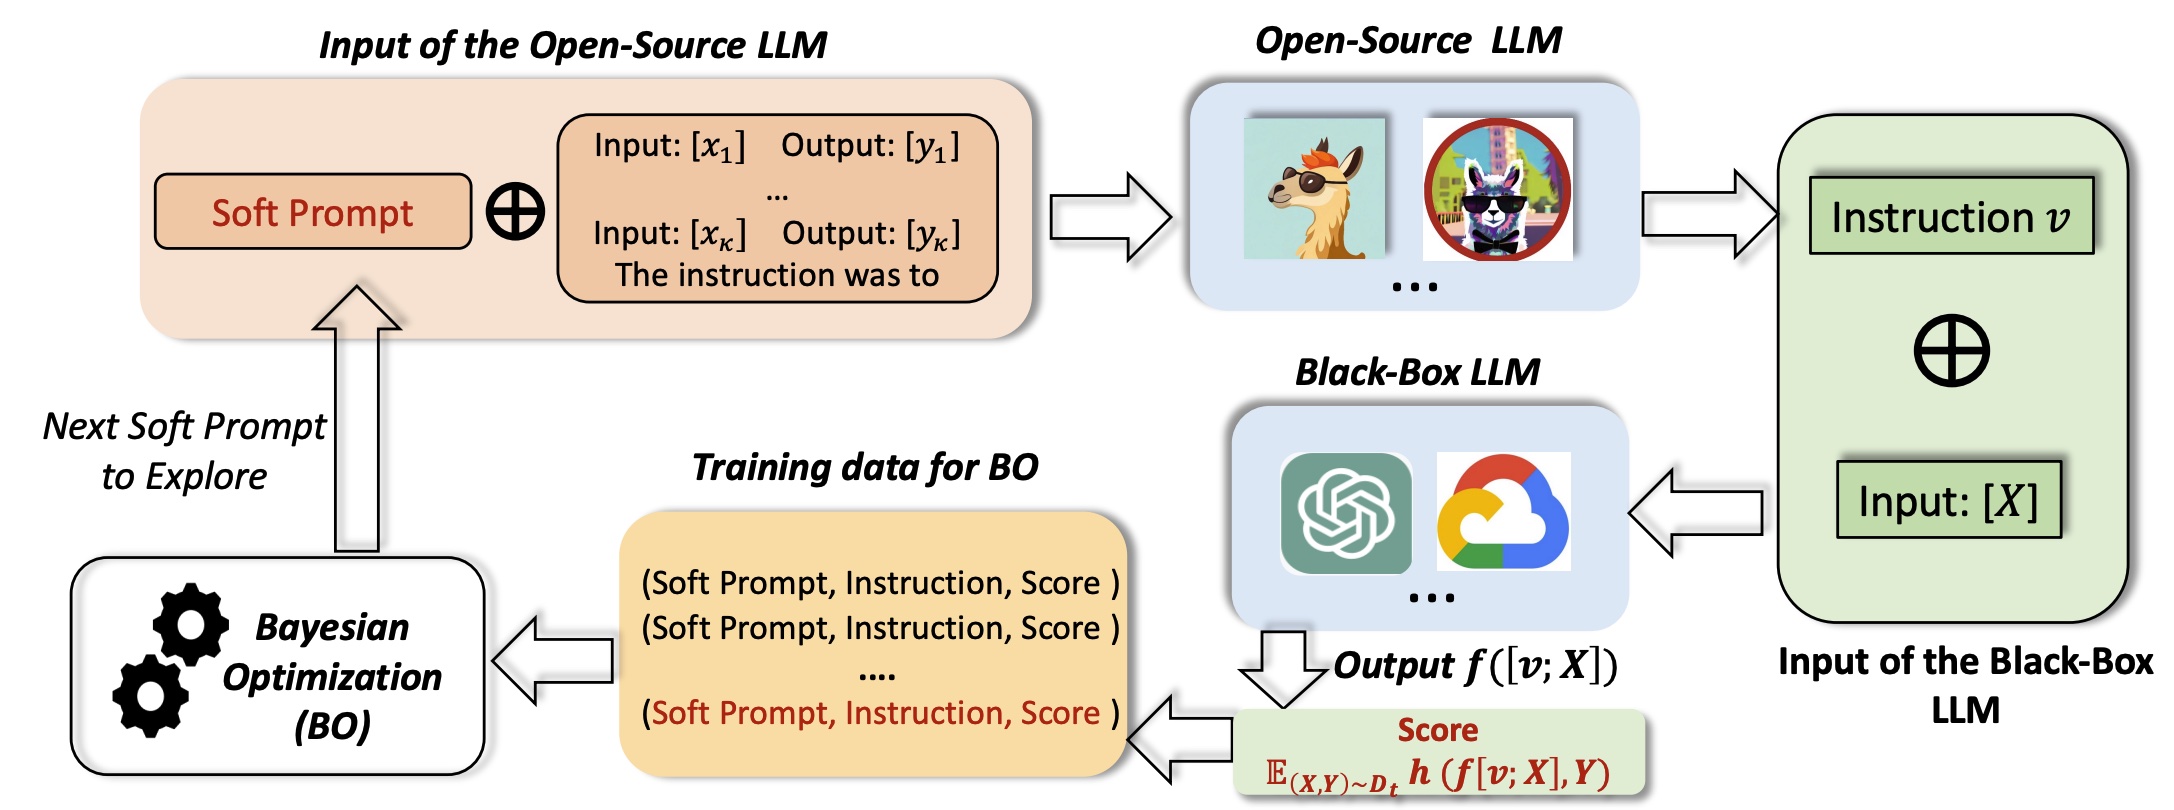
|
Lichang Chen*, Jiuhai Chen*, Tom Goldstein, Heng Huang, Tianyi Zhou ICML, 2024 |
|
Lichang Chen*, Shiyang Li*, Jun Yan, Hai Wang, Kalpa Gunaratna, Vikas Yadav, Zheng Tang, Vijay Srinivasan, Tianyi Zhou, Heng Huang, Hongxia Jin ICLR, 2024 |
|
Intern@Google Deepmind, Meta RL for reasoning & Thinking to Learn.
|
|
|